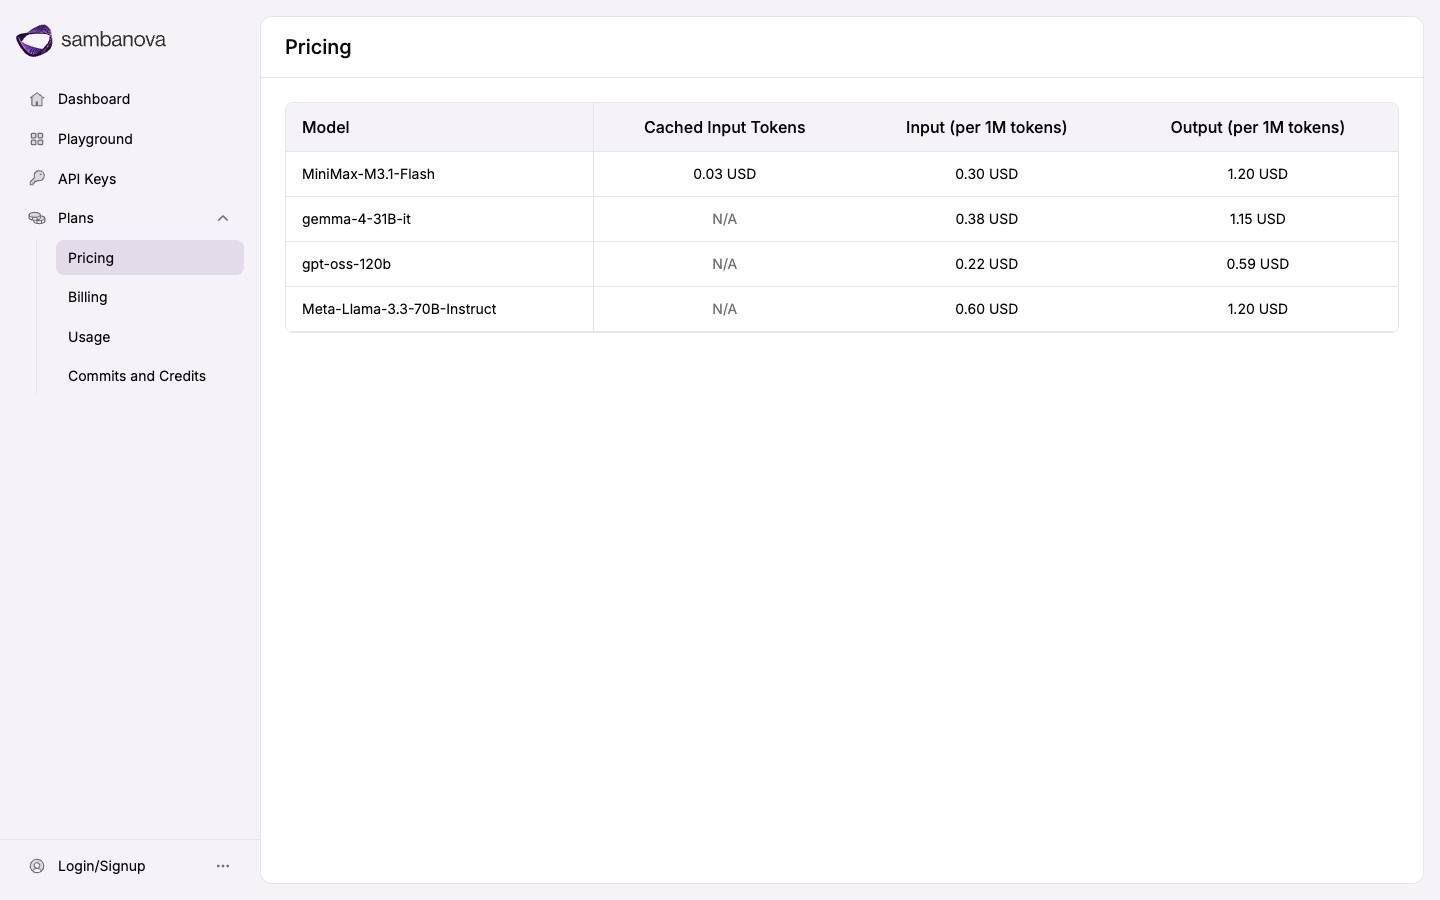
Captured November 4, 2026 at 1440px wide.
SambaNova plans and prices
| Plan | Price | Billing |
|---|---|---|
| MiniMax-M3.1-Flash | 0.30 USD | Input (per 1M tokens) |
| gemma-4-31B-it | 0.38 USD | Input (per 1M tokens) |
| gpt-oss-120b | 0.22 USD | Input (per 1M tokens) |
| Meta-Llama-3.3-70B-Instruct | 0.60 USD | Input (per 1M tokens) |
As printed on the page captured November 4, 2026.
How does SambaNova pricing work?
The value metric is the token, priced per million and split three ways in the column headers: 'Cached Input Tokens', 'Input (per 1M tokens)' and 'Output (per 1M tokens)'. Packaging is the model list itself. Four models, MiniMax-M3.1-Flash, gemma-4-31B-it, gpt-oss-120b and Meta-Llama-3.3-70B-Instruct, each carry their own rates, so choosing a model is choosing a price. Output runs above input on every row, about 2x on Meta-Llama-3.3-70B-Instruct (0.60 USD to 1.20 USD) and 4x on MiniMax-M3.1-Flash (0.30 USD to 1.20 USD), which follows the higher cost of generating a token than reading one.
The motion is self-serve, and the page lives inside the cloud console. A left nav runs 'Dashboard', 'Playground', 'API Keys', then 'Plans', which opens to 'Pricing', 'Billing', 'Usage' and 'Commits and Credits', with 'Login/Signup' at the foot. The page itself is an H1, 'Pricing', over one table. It is written for a developer who has already arrived: the rate card sits one click from an API key and a playground, and the buying journey is sign up, create a key, call a model.
Under the hood, this is a dimensional price: one meter, tokens, with the rate looked up by model and by token type. The cached input rate on MiniMax-M3.1-Flash, 0.03 USD against 0.30 USD for fresh input, passes the saving from prompt reuse to the buyer, and 'N/A' marks the three models where the page lists no cached rate. 'Commits and Credits' as its own page under Plans points to committed spend and prepaid balances beside pay-as-you-go, the route larger inference buyers take to a better rate. Worth borrowing: the rate card placed next to Billing and Usage, so the price, the meter and the bill share one menu.
What does SambaNova's pricing page do well?
- The column headers carry the unit, 'Input (per 1M tokens)' and 'Output (per 1M tokens)', so every cell reads as a rate without a footnote
- 'N/A' fills the cached column for gemma-4-31B-it, gpt-oss-120b and Meta-Llama-3.3-70B-Instruct, a stated answer in every cell
- Pricing sits in the console nav beside 'Billing', 'Usage' and 'Commits and Credits', so rate, meter and invoice are neighbors
- 'Playground' and 'API Keys' are one click from the rate card, so a developer can try a model at the price just read
What does SambaNova's pricing page reveal about its pricing strategy?
- A cached input rate of 0.03 USD against 0.30 USD on MiniMax-M3.1-Flash prices prompt reuse at a tenth of a fresh read
- Output-to-input ratios run from 2x to 4x by model, so each row carries that model's own serving economics
- gpt-oss-120b at 0.22 USD input sits below Meta-Llama-3.3-70B-Instruct at 0.60 USD, so rates follow the cost of serving each model, not the size in its name
- 'Commits and Credits' under Plans points to committed spend and prepaid balances sitting behind the per-token list
Learn with Orb
- ProductPrice modeling Each SambaNova model carries its own 'Cached Input Tokens', 'Input (per 1M tokens)' and 'Output (per 1M tokens)' rates, a dimensional price keyed by model and token type, the pricing logic Orb's price modeling is built to represent.
- GuidePay-as-you-go pricing for SaaS A four-row rate card one click from 'API Keys' and 'Playground' lets a developer start paying per token with no plan to choose, the low-barrier entry Orb's pay-as-you-go guide describes.
- GuideAn AI founder's guide to prepaid credits 'Commits and Credits' sits under Plans beside the per-token list, the choice between committing a dollar amount and buying credits that Orb's founder's guide to prepaid credits walks through.
Questions about SambaNova pricing
How much does SambaNova cost?
SambaNova's pricing starts at $0.22/1M input tokens. The page shows 4 plans.
What pricing model does SambaNova use?
SambaNova prices by usage. Buyers choose a plan and sign up on their own. Its plans are aimed mainly at developers.
Does SambaNova have a free plan?
SambaNova's pricing page shows no free plan or free trial. The lowest paid plan starts at $0.22/1M input tokens.
Does SambaNova offer an annual discount?
SambaNova's pricing page shows a single billing period. The listed prices start at $0.22/1M input tokens.
How is SambaNova's pricing page laid out?
The page shows 4 plans. The breakdown above marks 12 points on it: 6 things it does well and 6 insights into the pricing.
Does SambaNova discount cached input tokens?
Yes, for MiniMax-M3.1-Flash. The rate card lists "0.03 USD" per million cached input tokens against "0.30 USD" for standard input, a tenth of the fresh rate. The other three models, gemma-4-31B-it, gpt-oss-120b and Meta-Llama-3.3-70B-Instruct, show "N/A" in the cached column.
What does SambaNova charge for output tokens?
Output is priced per million tokens and varies by model. MiniMax-M3.1-Flash and Meta-Llama-3.3-70B-Instruct are "1.20 USD", gemma-4-31B-it is "1.15 USD" and gpt-oss-120b is "0.59 USD". Every model's output rate sits above its input rate.
Which models are on SambaNova Cloud's pricing page?
The rate card lists four models: MiniMax-M3.1-Flash, gemma-4-31B-it, gpt-oss-120b and Meta-Llama-3.3-70B-Instruct. Each has an input and an output rate per million tokens, and only MiniMax-M3.1-Flash has a cached input rate. The lowest input rate is "0.22 USD" on gpt-oss-120b.
From the page as captured November 4, 2026. Current prices are on cloud.sambanova.ai

AssemblyAI
$0.15/hrAssemblyAI bills speech-to-text by the hour of audio, the unit a transcription team already uses, and the default view shows two rates: Universal-3.5 Pro at $0.21 /hr and Universal-2 at $0.15 /hr. A selector across eight APIs, grouped under TRANSCRIBE, UNDERSTAND and INTERACT, swaps the rate table, so each product is priced in its own unit, from audio hours to LLM tokens to input characters. The FAQ carries the billing mechanics in plain words, including the new Text-to-Speech API at $15 per 1M characters.

Baseten
From $0.01/1M tokensBaseten layers a three-tier service ladder over published rate sheets. Basic is '$0 per month, pay as you go', and Pro and Enterprise carry 'Volume discounts available' with 'GET A QUOTE'. Underneath sit three meters: Model APIs per 1M tokens across 19 model rows with Input, Cache Input and Output columns, opening with joey-1 at $0.01 input, dedicated GPU and CPU instances billed 'down to the minute', and the same GPU grid for training.
Black Forest Labs
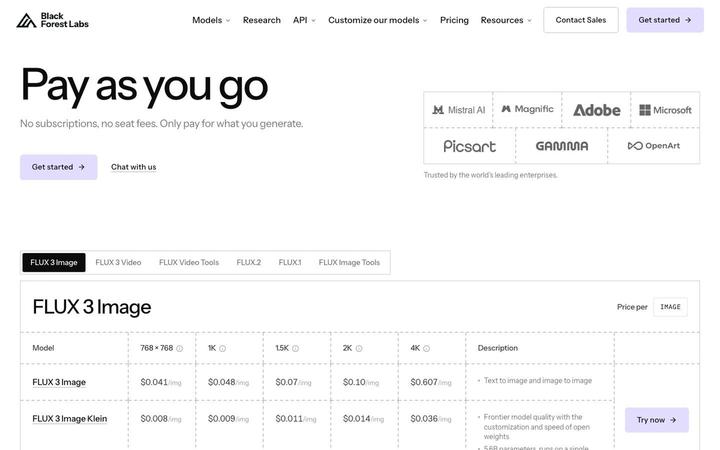
From $0.008/imgBlack Forest Labs sells FLUX image generation per image, priced by model and resolution: FLUX 3 Image runs from $0.041/img at 768 × 768 to $0.607/img at 4K, and FLUX 3 Image Klein from $0.008/img to $0.036/img. Below the API rate card sits a second business, Open Weights Licensing, packaged by images per month, domains and licensed users, with Builder and Platform available to purchase and three sales-led licenses above them.
Cohere
$3.00/instance/hrCohere prices for the enterprise in three shapes: custom contracts for its North and Compass platforms, reserved capacity on Model Vault at $3.00 to $7.00 an hour or $2,000 to $4,300 a month per instance, and pay-as-you-go tokens behind a Production API key. A four-way toggle sorts the page by buying job, and the FAQ carries the billing mechanics, down to an invoice at month end or at $250 of outstanding balance.
Deepgram
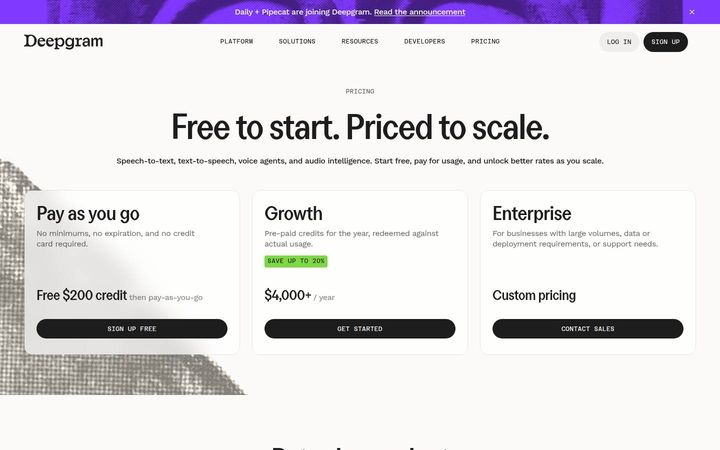
$0.0077/minDeepgram's page opens on "Free to start. Priced to scale." and three cards: Pay as you go with a Free $200 credit, Growth at $4,000+ / year in pre-paid credits for up to 20% off, and Enterprise at Custom pricing. A tabbed "Rates by product" section names the meter for each product, per second of audio, per 1,000 characters, or per minute of connection time, and a sixteen-question FAQ carries the billing mechanics, from hourly rates to the 10% overage premium.

Exa
$4/1k requestsExa prices its search API per thousand requests, with a rate for each endpoint: Lite Search $4, Auto Search $7, Deep Search $12, Contents $1 per 1k pages, Monitors $2 and Answer $5, plus $1 per 1k for each result above ten and for AI page summaries. Agent runs offer metered compute at $0.10 per ACU and six effort levels: five fixed from $0.012 to $1.00 per request and an Ultra level billed on usage. The plan cards divide access, throughput and compliance, and the rate card below them carries the price.