How Baseten prices
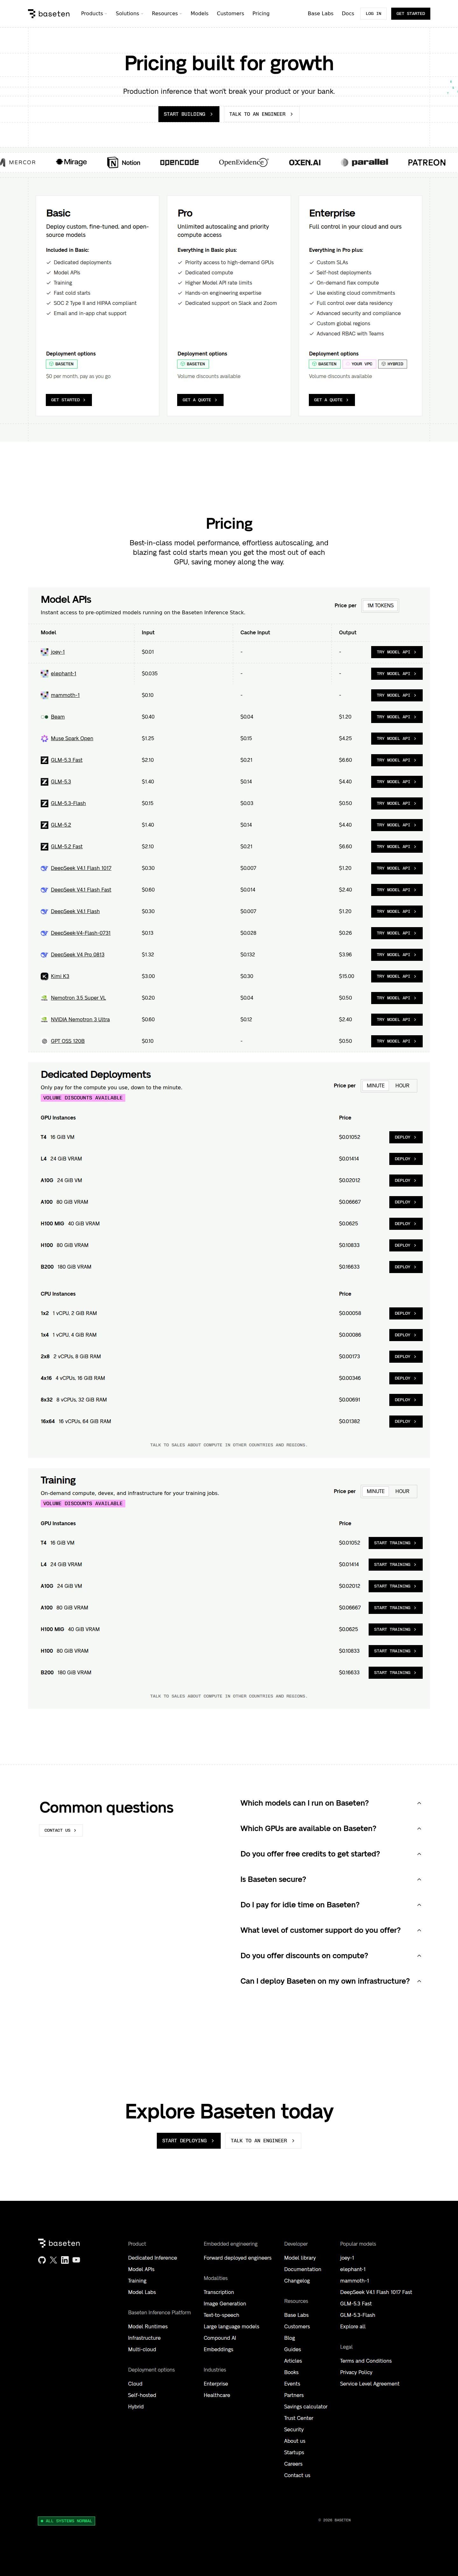
Captured November 2, 2026 at 1440px wide.
Baseten plans and prices
| Plan | Price | Billing |
|---|---|---|
| BasicDeploy custom, fine-tuned, and open-source models | $0 | per month, pay as you go |
| ProUnlimited autoscaling and priority compute access | Volume discounts available | |
| EnterpriseFull control in your cloud and ours | Volume discounts available |
As printed on the page captured November 2, 2026.
How does Baseten pricing work?
Baseten prices raw compute in three forms. Model APIs bill per 1M tokens, from joey-1 at $0.01 input, elephant-1 at $0.035 and mammoth-1 at $0.10, through GLM-5.3 at $1.40 input, $0.14 cache input and $4.40 output, Beam at $0.40, $0.04 and $1.20, and GPT OSS 120B at $0.10 input and $0.50 output. Dedicated Deployments bill per minute, from a T4 at $0.01052 to an H100 80 GiB at $0.10833 and a B200 180 GiB at $0.16633, with CPU instances from $0.00058 for 1 vCPU and 2 GiB. Training uses the same GPU grid. Per-minute billing fits a platform built on autoscaling and fast cold starts, since a customer pays for the replica time it runs: 'Only pay for the compute you use, down to the minute.'
The tiers sell service and control around that usage. Basic includes 'Dedicated deployments', 'Model APIs', 'Training', 'Fast cold starts', 'SOC 2 Type II and HIPAA compliant' and 'Email and in-app chat support'. Pro adds 'Priority access to high-demand GPUs', 'Dedicated compute', 'Higher Model API rate limits' and 'Dedicated support on Slack and Zoom'. Enterprise adds 'Custom SLAs', 'Self-host deployments', 'Use existing cloud commitments' and 'Full control over data residency', with BASETEN, YOUR VPC and HYBRID deployment options. 'Pricing built for growth' sits over 'START BUILDING' and 'TALK TO AN ENGINEER', a logo row runs Mercor, Mirage, Notion, OpenCode, OpenEvidence, Oxen.ai, Parallel and Patreon, and every rate row carries its own action: 'TRY MODEL API', 'DEPLOY' or 'START TRAINING'.
The commercial layer is a usage platform with negotiated pricing on top. There is no platform fee on Basic, so revenue is pure consumption, and Pro and Enterprise trade commitment for 'Volume discounts available', so committed spend earns a lower rate. 'Use existing cloud commitments' on Enterprise lets a customer apply cloud spend it has already committed, and compute in other countries and regions is arranged with sales. The Model API table prices four things per model: size, with joey-1, elephant-1 and mammoth-1 stepping from $0.01 to $0.035 to $0.10 on input alone; speed, with GLM-5.3 Fast at $2.10 input against $1.40 for GLM-5.3 and DeepSeek V4.1 Flash Fast at $0.60 against $0.30; caching, with DeepSeek V4.1 Flash cache input at $0.007 against $0.30 input; and freshness, with dated builds such as DeepSeek V4.1 Flash 1017 listed as their own rows. Rate tables for AI are growing more dimensions as serving costs split by workload, and this table prints each one.
What does Baseten's pricing page do well?
- Basic is '$0 per month, pay as you go', so the only cost is metered usage
- Model API pricing prints Input, Cache Input and Output per 1M tokens, and joey-1, elephant-1 and mammoth-1 carry a single input rate, so each row shows exactly which tokens are billed
- Fast variants (GLM-5.3 Fast, GLM-5.2 Fast, DeepSeek V4.1 Flash Fast) sit as their own rows beside the standard models, so speed has a visible price
- Dedicated deployment prices are quoted per minute with a MINUTE / HOUR switch across seven GPU classes and six CPU shapes
- Every rate row has a direct action ('TRY MODEL API', 'DEPLOY', 'START TRAINING'), so a developer moves from a price to using it in one click
What does Baseten's pricing page reveal about its pricing strategy?
- Three meters for three workloads: tokens for Model APIs, GPU minutes for dedicated inference, and the same minutes for training, with no platform fee on Basic
- joey-1, elephant-1 and mammoth-1 at $0.01, $0.035 and $0.10 input form a size ladder priced on the prompt alone. That points to models whose cost sits in the tokens they read
- 'Volume discounts available' on Pro and Enterprise, plus 'Use existing cloud commitments', point to committed-spend contracts with lower unit rates
- DeepSeek V4.1 Flash cache input at $0.007 against $0.30 input, and GLM-5.3 at a tenth of input, show token pricing splitting by serving cost
- Fast rows at 1.5x to 2x the standard input rate turn latency into a priced SKU on the same meter
Learn with Orb
- ProductPrice modeling Tokens split into input, cache input and output rates, and seven GPU classes bill by the minute; Orb's price modeling covers dimensional rates like these across one catalog.
- GuidePay-as-you-go pricing for SaaS Basic is $0 a month and pay as you go, so consumption is the whole bill; Orb's guide covers how pay-as-you-go lowers the barrier to entry and scales revenue with use.
- DocsConfiguring plans: minimums and plan phases Volume discounts on Pro and Enterprise point to committed-spend contracts; Orb represents a dollar commitment as a minimum and uses plan phases to step it up on a schedule.
Questions about Baseten pricing
How much does Baseten cost?
Baseten's pricing starts at $0.01/1M tokens. The page shows 3 plans, with the top plan priced through sales.
What pricing model does Baseten use?
Baseten prices by usage, combined with flat-rate tiers. Buyers can sign up on their own or go through the sales team. Its plans are aimed mainly at developers.
Does Baseten have a free plan?
Baseten's pricing page shows no free plan or free trial. The lowest paid plan starts at $0.01/1M tokens.
Does Baseten offer an annual discount?
Baseten's pricing page shows a single billing period. The listed prices start at $0.01/1M tokens. Terms for the plans priced through sales are set with the sales team.
How is Baseten's pricing page laid out?
The page shows 3 plans and includes an FAQ. The breakdown above marks 14 points on it: 9 things it does well and 5 insights into the pricing.
Does Baseten bill GPU time by the minute?
Yes, Baseten bills Dedicated Deployments and Training by the minute, with the page stating "Only pay for the compute you use, down to the minute". An H100 80 GiB VRAM instance is listed at $0.10833 per minute, and a T4 16 GiB VM starts at $0.01052 per minute. Both sections also carry the note "VOLUME DISCOUNTS AVAILABLE".
How much do joey-1, elephant-1 and mammoth-1 cost on Baseten?
Baseten lists joey-1 at $0.01, elephant-1 at $0.035 and mammoth-1 at $0.10 per 1M input tokens in its Model APIs table. The Cache Input and Output columns show a dash for all three, so the printed rate is the input price. Each row carries a "TRY MODEL API" button.
Can I run Baseten in my own cloud or VPC?
Yes, the Enterprise plan offers deployment options of Baseten, your VPC, and hybrid. Enterprise includes "Self-host deployments", "Use existing cloud commitments" and "Full control over data residency", along with "Custom SLAs" and "Custom global regions". Pricing is arranged through "GET A QUOTE", with "Volume discounts available".
From the page as captured November 2, 2026. Current prices are on baseten.co
Together AI
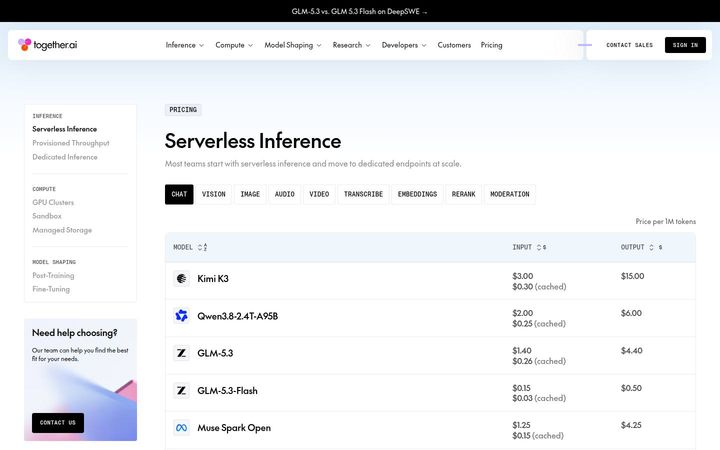
From $0.04/1M tokensTogether AI prices eight products on one page, each on the unit that drives its cost: per-token serverless rates across 29 chat models, reserved throughput in PTUs at $0.05 per minute, GPU hours banded by commitment length, post-training GPU hours billed per minute, sandbox vCPU and RAM hours, filesystem storage per GiB and fine-tuning per million tokens with a per-job minimum. The page shows its working throughout, from cached input rates inline to the stated assumptions behind the PTU estimator and the rule for counting fine-tuning tokens.

AssemblyAI
$0.15/hrAssemblyAI bills speech-to-text by the hour of audio, the unit a transcription team already uses, and the default view shows two rates: Universal-3.5 Pro at $0.21 /hr and Universal-2 at $0.15 /hr. A selector across eight APIs, grouped under TRANSCRIBE, UNDERSTAND and INTERACT, swaps the rate table, so each product is priced in its own unit, from audio hours to LLM tokens to input characters. The FAQ carries the billing mechanics in plain words, including the new Text-to-Speech API at $15 per 1M characters.
Cohere
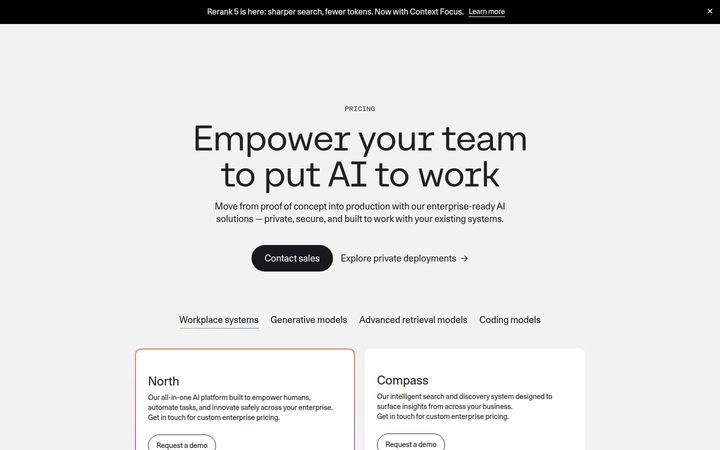
$3.00/instance/hrCohere prices for the enterprise in three shapes: custom contracts for its North and Compass platforms, reserved capacity on Model Vault at $3.00 to $7.00 an hour or $2,000 to $4,300 a month per instance, and pay-as-you-go tokens behind a Production API key. A four-way toggle sorts the page by buying job, and the FAQ carries the billing mechanics, down to an invoice at month end or at $250 of outstanding balance.
Deepgram
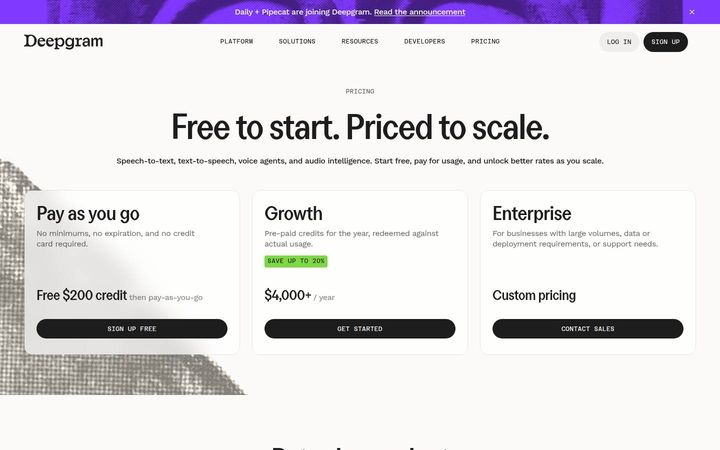
$0.0077/minDeepgram's page opens on "Free to start. Priced to scale." and three cards: Pay as you go with a Free $200 credit, Growth at $4,000+ / year in pre-paid credits for up to 20% off, and Enterprise at Custom pricing. A tabbed "Rates by product" section names the meter for each product, per second of audio, per 1,000 characters, or per minute of connection time, and a sixteen-question FAQ carries the billing mechanics, from hourly rates to the 10% overage premium.

Exa
$4/1k requestsExa prices its search API per thousand requests, with a rate for each endpoint: Lite Search $4, Auto Search $7, Deep Search $12, Contents $1 per 1k pages, Monitors $2 and Answer $5, plus $1 per 1k for each result above ten and for AI page summaries. Agent runs offer metered compute at $0.10 per ACU and six effort levels: five fixed from $0.012 to $1.00 per request and an Ultra level billed on usage. The plan cards divide access, throughput and compliance, and the rate card below them carries the price.
fal
From $0.0002/secondfal prices two products on one page with rate sheets in place of plans: GPU hours for serverless compute across six SKUs, and model APIs billed per output unit across video, image, audio and 3D. The "Units per $1" column turns seconds, tokens, images, megapixels, characters, generations and credits into one number a buyer compares directly.