Captured November 4, 2026 at 1440px wide.
Thinking Machines plans and prices
| Plan | Price | Billing |
|---|---|---|
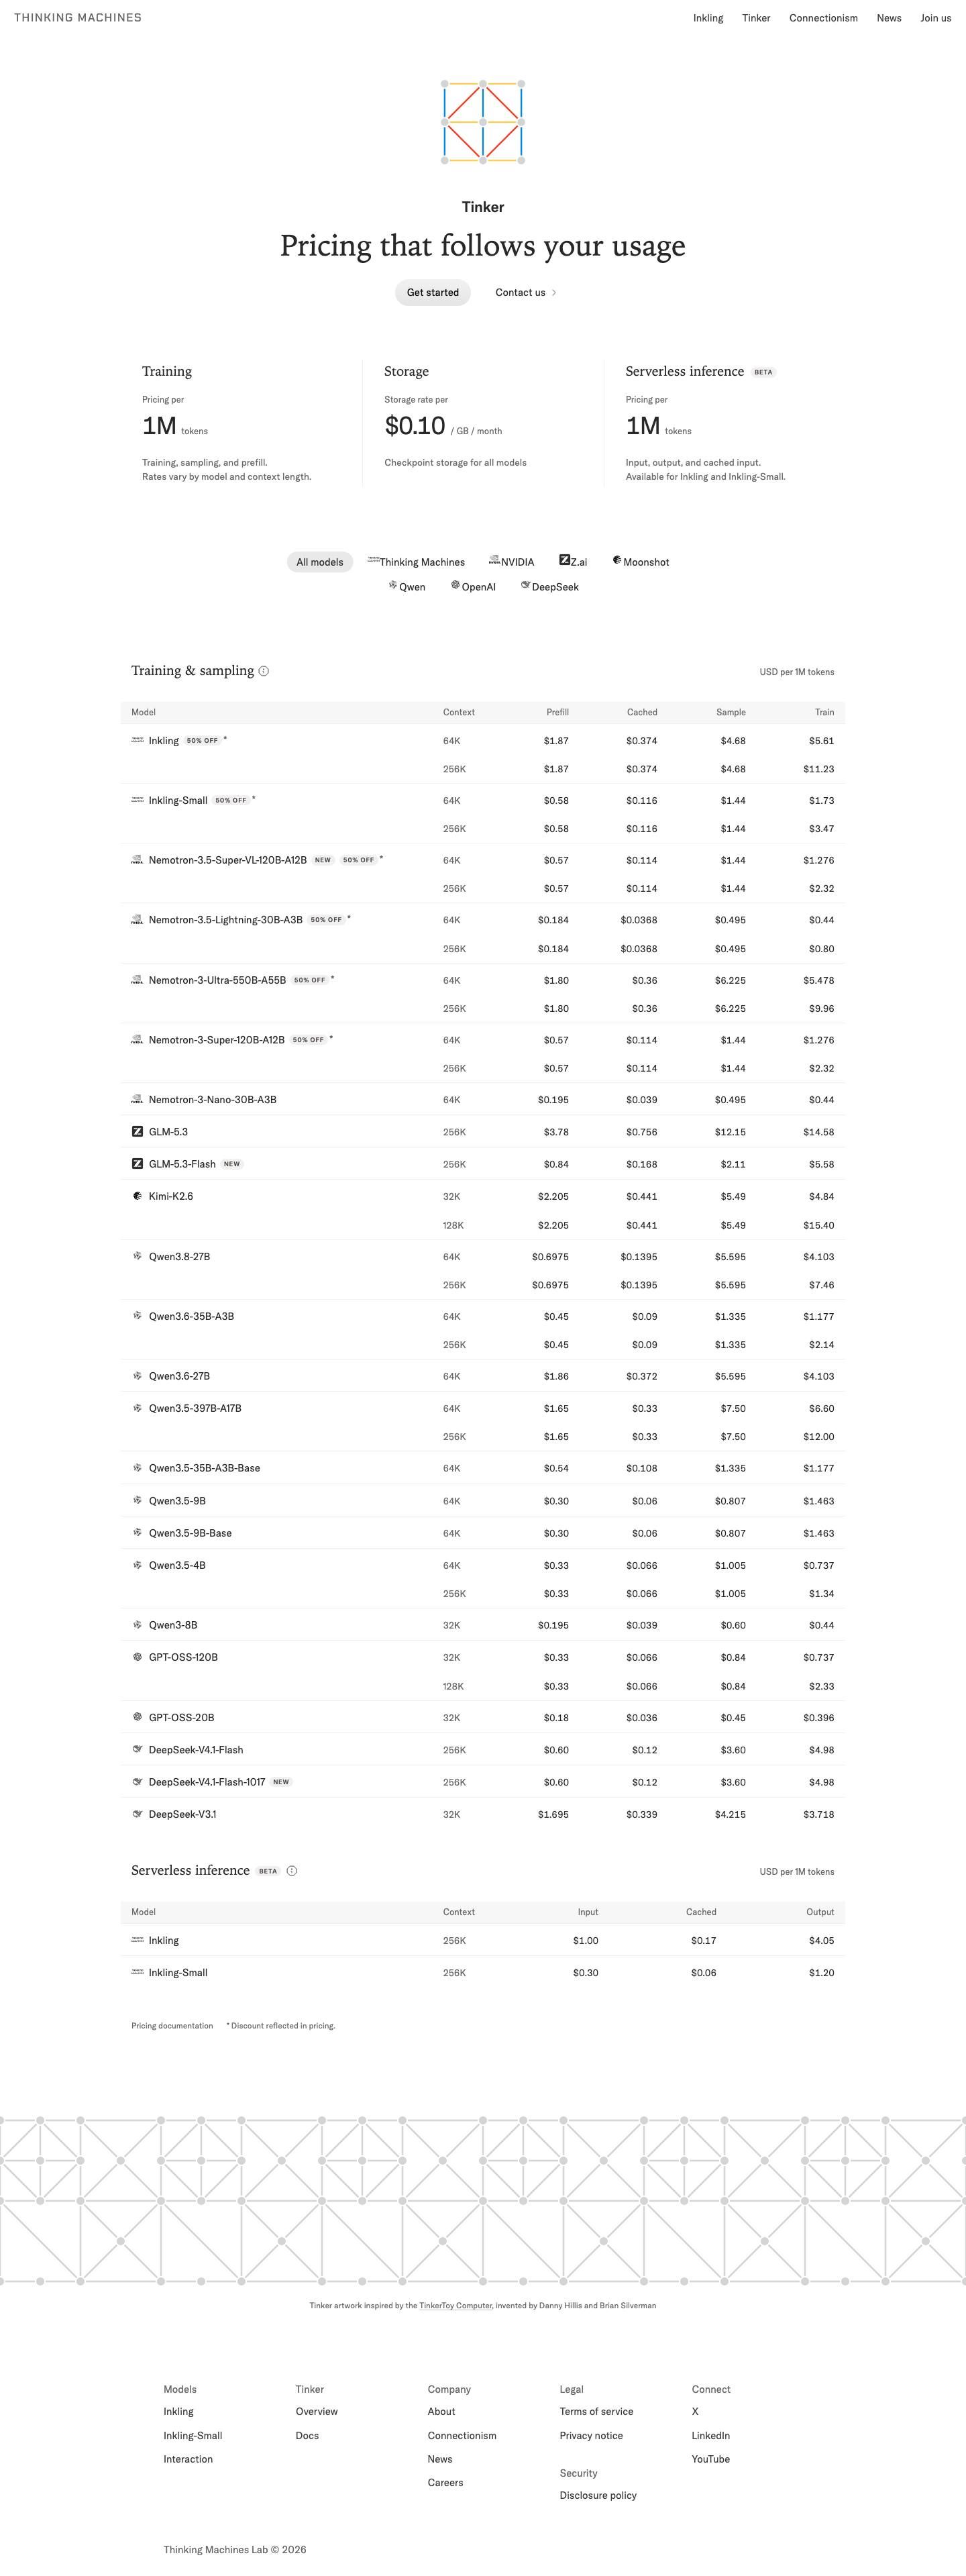
| TrainingTraining, sampling, and prefill. | — | Pricing per 1M tokens |
| StorageCheckpoint storage for all models | $0.10 | / GB / month |
| Serverless inferenceInput, output, and cached input. | — | Pricing per 1M tokens |
| Inkling | $1.87 | USD per 1M tokens |
| Inkling-Small | $0.58 | USD per 1M tokens |
| GPT-OSS-20B | $0.18 | USD per 1M tokens |
As printed on the page captured November 4, 2026.
How does Thinking Machines pricing work?
The value metric is the token, counted separately for each step of a training loop. The 'Training & sampling' table prices 'Prefill', 'Cached', 'Sample' and 'Train' per million tokens for every model and context length, from GPT-OSS-20B at $0.18 prefill and $0.396 train up to GLM-5.3 at $3.78 prefill and Kimi-K2.6 at $15.40 train with a 128K context. Packaging is three products, set out as cards under the headline: 'Training' with 'Rates vary by model and context length.', 'Storage' at '$0.10 / GB / month' for 'Checkpoint storage for all models', and 'Serverless inference BETA', 'Available for Inkling and Inkling-Small.' There are no plans or tiers; the model and its context window set the price.
The motion is self-serve. 'Tinker' and 'Pricing that follows your usage' sit over 'Get started' and 'Contact us', and the rest of the page is reference: the three summary cards, a filter row of 'All models', 'Thinking Machines', 'NVIDIA', 'Z.ai', 'Moonshot', 'Qwen', 'OpenAI' and 'DeepSeek', the long training table, the two-row inference table, and a footer with 'Pricing documentation' and '* Discount reflected in pricing.' The page signals a research-grade audience who wants the full rate matrix and will do the arithmetic for a training run.
Under the hood, the rate card is a matrix of model by context by meter. Cached prefill is one fifth of prefill on every row, $1.87 to $0.374 on Inkling and $0.58 to $0.116 on Inkling-Small, a flat rule for prompt reuse. Context length moves only the training rate: Inkling trains at $5.61 at 64K and $11.23 at 256K while prefill and sample hold at $1.87 and $4.68, and the 64K rows carry '50% OFF*'. Storage then bills the checkpoint a training run leaves behind, a recurring line that continues after training ends, and serverless inference turns those checkpoints into per-token revenue on the lab's own models. Worth borrowing: a dated rate table and one discount rule applied the same way across the catalog.
What does Thinking Machines' pricing page do well?
- Three summary cards state each unit before the detail: 'Pricing per 1M tokens', '$0.10 / GB / month' and 'Pricing per 1M tokens'
- A provider filter, 'All models' through 'DeepSeek', narrows a 24-model table to one family
- Each table names its unit and date: 'Training & sampling prices in US dollars per million tokens, as of October 19, 2026'
- 'NEW' and '50% OFF*' badges sit on the model rows they apply to, with '* Discount reflected in pricing.' in the footer
- 'Pricing documentation' links from the foot of the rate tables for the full billing rules
What does Thinking Machines' pricing page reveal about its pricing strategy?
- Four meters per model, 'Prefill', 'Cached', 'Sample' and 'Train', price each step of a training loop at its own cost
- Cached prefill is a fixed one fifth of prefill on every row, a single rule for prompt reuse across the catalog
- Context length changes only the train rate, $5.61 at 64K against $11.23 at 256K on Inkling, so long-context training carries its own price
- Checkpoint storage at $0.10 / GB / month adds recurring revenue that continues after a training run ends
- Serverless inference 'Available for Inkling and Inkling-Small' pairs a broad training catalog with paid serving of the lab's own models
Learn with Orb
- ProductPrice modeling Tinker prices 'Prefill', 'Cached', 'Sample' and 'Train' per model and context length, a matrix of dimensional rates that Orb's price modeling represents and changes without re-engineering billing.
- ProductPrice evolution A rate card dated 'as of October 19, 2026', with 'NEW' models and '50% OFF*' rows, is pricing that changes on a schedule, the rollout Orb's price evolution product helps customers plan around.
- Guide14 usage-based pricing examples 'Pricing that follows your usage' heads per-token training rates and '$0.10 / GB / month' checkpoint storage, two meters of the kind Orb's usage-based pricing examples catalog.
Questions about Thinking Machines pricing
How much does Thinking Machines cost?
Thinking Machines' pricing starts at $0.036/1M tokens. The page shows 3 plans.
What pricing model does Thinking Machines use?
Thinking Machines prices by usage. Buyers choose a plan and sign up on their own. Its plans are aimed mainly at developers.
Does Thinking Machines have a free plan?
Thinking Machines' pricing page shows no free plan or free trial. The lowest paid plan starts at $0.036/1M tokens.
Does Thinking Machines offer an annual discount?
Thinking Machines' pricing page shows a single billing period. The listed prices start at $0.036/1M tokens.
How is Thinking Machines' pricing page laid out?
The page shows 3 plans. The breakdown above marks 14 points on it: 6 things it does well and 8 insights into the pricing.
Why does Tinker training cost more at 256K context?
Tinker sets its train rate by context length while prefill and sample stay the same. Inkling trains at $5.61 per million tokens at 64K and $11.23 at 256K, with prefill at $1.87 and sample at $4.68 for both. The 64K rows carry a "50% OFF*" badge, and the footnote reads "* Discount reflected in pricing."
What does Tinker charge for checkpoint storage?
Storage is "$0.10 / GB / month", listed as "Checkpoint storage for all models". It sits beside training and serverless inference as its own meter. The charge applies per gigabyte for each month a checkpoint is kept.
What are the rates for Tinker serverless inference?
Serverless inference is in beta and "Available for Inkling and Inkling-Small." Inkling is $1.00 input, $0.17 cached input and $4.05 output per million tokens. Inkling-Small is $0.30 input, $0.06 cached and $1.20 output, both with a 256K context.
From the page as captured November 4, 2026. Current prices are on thinkingmachines.ai

AssemblyAI
$0.15/hrAssemblyAI bills speech-to-text by the hour of audio, the unit a transcription team already uses, and the default view shows two rates: Universal-3.5 Pro at $0.21 /hr and Universal-2 at $0.15 /hr. A selector across eight APIs, grouped under TRANSCRIBE, UNDERSTAND and INTERACT, swaps the rate table, so each product is priced in its own unit, from audio hours to LLM tokens to input characters. The FAQ carries the billing mechanics in plain words, including the new Text-to-Speech API at $15 per 1M characters.

Baseten
From $0.01/1M tokensBaseten layers a three-tier service ladder over published rate sheets. Basic is '$0 per month, pay as you go', and Pro and Enterprise carry 'Volume discounts available' with 'GET A QUOTE'. Underneath sit three meters: Model APIs per 1M tokens across 19 model rows with Input, Cache Input and Output columns, opening with joey-1 at $0.01 input, dedicated GPU and CPU instances billed 'down to the minute', and the same GPU grid for training.
Black Forest Labs
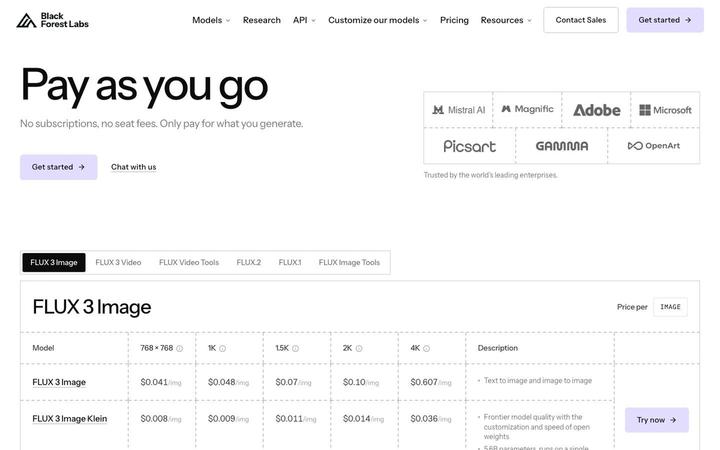
From $0.008/imgBlack Forest Labs sells FLUX image generation per image, priced by model and resolution: FLUX 3 Image runs from $0.041/img at 768 × 768 to $0.607/img at 4K, and FLUX 3 Image Klein from $0.008/img to $0.036/img. Below the API rate card sits a second business, Open Weights Licensing, packaged by images per month, domains and licensed users, with Builder and Platform available to purchase and three sales-led licenses above them.
Cohere
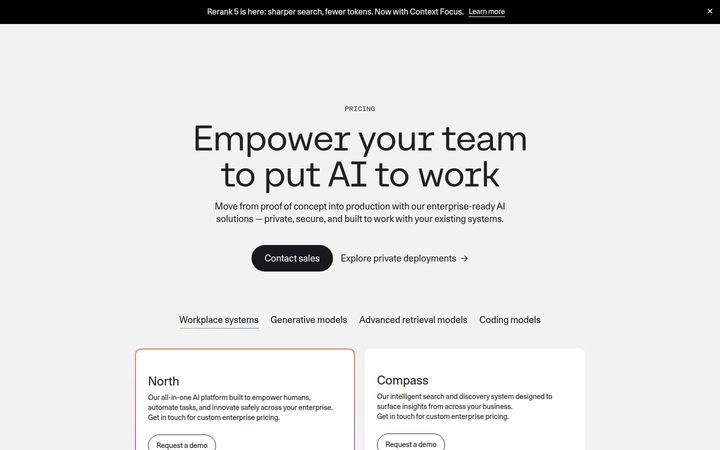
$3.00/instance/hrCohere prices for the enterprise in three shapes: custom contracts for its North and Compass platforms, reserved capacity on Model Vault at $3.00 to $7.00 an hour or $2,000 to $4,300 a month per instance, and pay-as-you-go tokens behind a Production API key. A four-way toggle sorts the page by buying job, and the FAQ carries the billing mechanics, down to an invoice at month end or at $250 of outstanding balance.
Deepgram
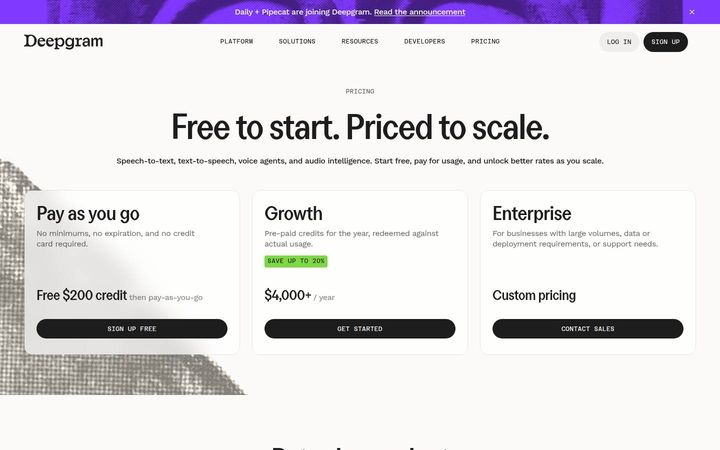
$0.0077/minDeepgram's page opens on "Free to start. Priced to scale." and three cards: Pay as you go with a Free $200 credit, Growth at $4,000+ / year in pre-paid credits for up to 20% off, and Enterprise at Custom pricing. A tabbed "Rates by product" section names the meter for each product, per second of audio, per 1,000 characters, or per minute of connection time, and a sixteen-question FAQ carries the billing mechanics, from hourly rates to the 10% overage premium.

Exa
$4/1k requestsExa prices its search API per thousand requests, with a rate for each endpoint: Lite Search $4, Auto Search $7, Deep Search $12, Contents $1 per 1k pages, Monitors $2 and Answer $5, plus $1 per 1k for each result above ten and for AI page summaries. Agent runs offer metered compute at $0.10 per ACU and six effort levels: five fixed from $0.012 to $1.00 per request and an Ultra level billed on usage. The plan cards divide access, throughput and compliance, and the rate card below them carries the price.