How Together AI prices
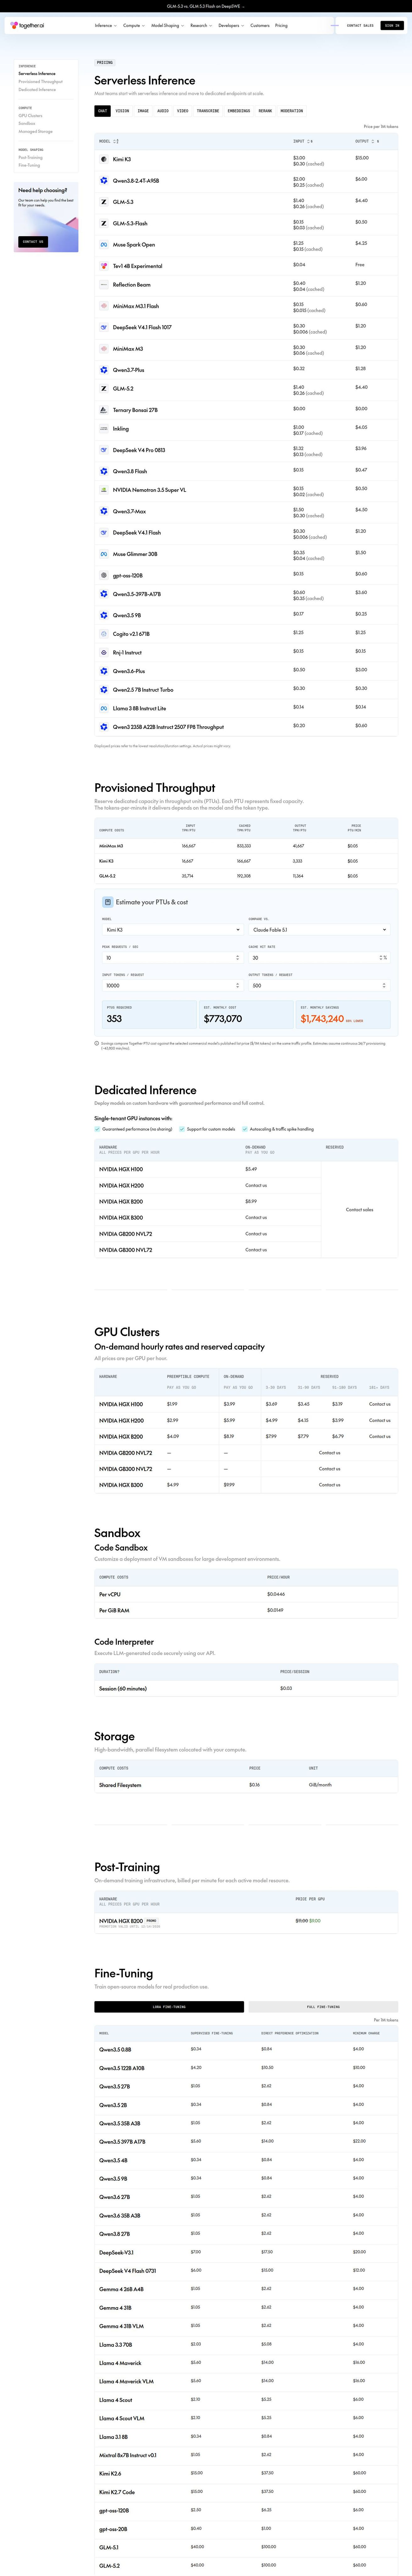
Captured October 26, 2026 at 1440px wide. The page continues below the crop (10,779px in total).
Together AI plans and prices
| Plan | Price | Billing |
|---|---|---|
| Kimi K3 | $3.00 | Price per 1M tokens |
| Qwen3.8-2.4T-A95B | $2.00 | Price per 1M tokens |
| GLM-5.3 | $1.40 | Price per 1M tokens |
| GLM-5.3-Flash | $0.15 | Price per 1M tokens |
| Muse Spark Open | $1.25 | Price per 1M tokens |
| Tev1 4B Experimental | $0.04 | Price per 1M tokens |
| Reflection Beam | $0.40 | Price per 1M tokens |
| MiniMax M3.1 Flash | $0.15 | Price per 1M tokens |
As printed on the page captured October 26, 2026.
How does Together AI pricing work?
Every product is metered on its own resource. Serverless Inference is per million tokens with separate input, cached input and output rates, so MiniMax M3 reads '$0.30' input, '$0.06 (cached)' and '$1.20' output, and Tev1 4B Experimental reads '$0.04' input with 'Free' output. Provisioned Throughput sells reserved capacity in PTUs at '$0.05' per PTU per minute, with a per-model table of how many tokens per minute each PTU delivers: 166,667 input TPM for MiniMax M3 and 16,667 for Kimi K3. Dedicated Inference, GPU Clusters and Post-Training are per GPU per hour, and Post-Training is 'billed per minute for each active model resource'. Sandbox is '$0.0446' per vCPU and '$0.0149' per GiB RAM, Code Interpreter is '$0.03' per 60-minute session, and storage is '$0.16 GiB/month'. Fine-tuning is per million training tokens, split into supervised and preference optimization rates, with a minimum charge per job. Elastic per-token rates and reserved capacity sit side by side, so a team can price both ends of an inference workload.
The page is laid out like a product catalog. A sticky sidebar groups the eight products under INFERENCE, COMPUTE and MODEL SHAPING, with a 'Need help choosing?' card and a CONTACT US button beneath it, and the top nav carries CONTACT SALES and SIGN IN. 'Most teams start with serverless inference and move to dedicated endpoints at scale' sets the journey in one line: adopt per token, then graduate to reserved or dedicated capacity as volume grows. Serverless opens with nine modality tabs, CHAT through MODERATION, and a model table labeled 'Price per 1M tokens'. Provisioned Throughput follows with its PTU conversion table and estimator, then the hardware tables, Sandbox, Storage, Post-Training and Fine-Tuning, a TRUSTED BY logo band, and a closing 'Start building on Together AI' band with GET STARTED NOW.
The GPU tables show how Together prices commitment. GPU Clusters spreads the H100 across five columns, '$1.99' preemptible, '$3.99' on demand, then '$3.69', '$3.45' and '$3.19' as the reserved term runs from 3 to 180 days, the H200 and B200 follow the same curve, and the HGX B300 now carries '$4.99' preemptible and '$9.99' on demand. Terms of 181+ days, the rack-scale GB200 NVL72 and GB300 NVL72, and Dedicated Inference reservations are set with sales, which keeps room to shape the longest and largest commitments deal by deal. Post-Training launches with '$11.00' struck through beside a '$9.00' promotional rate, which anchors the list price while inviting early training runs. The PTU estimator turns reservation into a capacity plan: peak requests per second, cache hit rate and tokens per request in, PTUs required and monthly cost out, with its basis written beneath it. Publishing the discount curve for each term length is the most borrowable idea here, because a buyer can see what each extra month of commitment is worth.
What does Together AI's pricing page do well?
- Cached input is priced inline next to standard input, for example '$0.15' and '$0.015 (cached)' on MiniMax M3.1 Flash, so a developer can design for prompt caching before writing code
- GPU Clusters prices the H100 at five commitment levels, $1.99 preemptible through $3.19 at 91 to 180 days, which prints the value of each longer term
- Post-Training states its billing granularity in the subhead, 'billed per minute for each active model resource', beside a per-GPU-hour rate
- The PTU estimator states its basis in writing, including continuous 24/7 provisioning at '~43,800 min/mo'
- Fine-tuning shows a MINIMUM CHARGE column per model and defines billable tokens as dataset size times epochs plus evaluation tokens
What does Together AI's pricing page reveal about its pricing strategy?
- Eight products, each on its own unit: tokens, PTU minutes, GPU hours, per-minute post-training GPU time, vCPU hours, sessions, GiB-months and training tokens, each tied to what it costs Together to serve
- The H100 curve from $3.99 on demand to $3.19 at 91 to 180 days shows commitment priced as a published discount ladder, now starting at a 3-day term
- Rack-scale systems and terms of 181+ days are set with sales, which keeps room to allocate scarce capacity and shape the largest deals
- A struck-through '$11.00' beside '$9.00' with a dated end anchors the Post-Training list rate while the promotion seeds adoption
- The sequencing line, serverless first and dedicated at scale, is a land-and-expand path written into the page header
Learn with Orb
- ProductExperience Kit The PTU estimator turns peak requests per second, cache hit rate and tokens per request into PTUs and a monthly cost; Experience Kit gives customers calculators like this to plan spend before they reserve.
- GuidePricing AI agents: plans, costs and monetization models Serverless rates split input, cached input and output per million tokens across 27 chat models; Orb's guide covers how teams meter AI work that arrives per call, token and event.
- GuideAn AI founder's guide to prepaid credits The H100 runs from $3.99 on demand to $3.19 at 91 to 180 days, commitment priced as a published ladder; the guide covers how a larger commitment earns a better rate.
Questions about Together AI pricing
How much does Together AI cost?
Together AI's pricing starts at $0.04/1M tokens. The page shows 8 plans, with the top plan priced through sales.
What pricing model does Together AI use?
Together AI prices by usage, combined with flat-rate tiers. Buyers can sign up on their own or go through the sales team. Its plans are aimed mainly at developers.
Does Together AI have a free plan?
Together AI's pricing page shows no free plan or free trial. The lowest paid plan starts at $0.04/1M tokens.
Does Together AI offer an annual discount?
Together AI's pricing page shows a single billing period. The listed prices start at $0.04/1M tokens. Terms for the plans priced through sales are set with the sales team.
How is Together AI's pricing page laid out?
The page shows 8 plans and includes a comparison table and a calculator. The breakdown above marks 14 points on it: 8 things it does well and 6 insights into the pricing.
How does Together AI Provisioned Throughput pricing work?
Together AI sells reserved capacity in throughput units (PTUs) at $0.05 per PTU per minute. The tokens per minute each PTU delivers depends on the model and token type, for example MiniMax M3 delivers 166,667 input, 833,333 cached and 41,667 output tokens per minute per PTU. The page includes an estimator that takes peak requests per second, cache hit rate and tokens per request and returns PTUs required and estimated monthly cost, assuming "continuous 24/7 provisioning (~43,800 min/mo)".
How is Together AI fine-tuning billed and is there a minimum charge?
Together AI prices fine-tuning per 1M tokens, with separate rates for supervised fine-tuning and direct preference optimization, such as $0.34 and $0.84 for Llama 3.1 8B. Billable tokens are the training dataset size times the number of epochs, plus any tokens in the optional evaluation dataset. Each job carries the minimum charge listed for its model, which ranges from $4.00 for smaller models up to $60.00 for models like Kimi K2.6 and GLM-5.2.
How much cheaper are Together AI GPU Clusters with a reserved term?
Together AI GPU Clusters prices the NVIDIA HGX H100 at $3.99 per GPU per hour on demand, $3.69 for 3-30 days, $3.45 for 31-90 days and $3.19 for 91-180 days, with preemptible compute at $1.99. The H200 and B200 follow the same ladder, for example the B200 runs from $8.19 on demand to $6.79 at 91-180 days. Terms of 181+ days and the GB200 NVL72 and GB300 NVL72 systems are priced through the Contact us option.
From the page as captured October 26, 2026. Current prices are on together.ai

Baseten
From $0.01/1M tokensBaseten layers a three-tier service ladder over published rate sheets. Basic is '$0 per month, pay as you go', and Pro and Enterprise carry 'Volume discounts available' with 'GET A QUOTE'. Underneath sit three meters: Model APIs per 1M tokens across 19 model rows with Input, Cache Input and Output columns, opening with joey-1 at $0.01 input, dedicated GPU and CPU instances billed 'down to the minute', and the same GPU grid for training.

AssemblyAI
$0.15/hrAssemblyAI bills speech-to-text by the hour of audio, the unit a transcription team already uses, and the default view shows two rates: Universal-3.5 Pro at $0.21 /hr and Universal-2 at $0.15 /hr. A selector across eight APIs, grouped under TRANSCRIBE, UNDERSTAND and INTERACT, swaps the rate table, so each product is priced in its own unit, from audio hours to LLM tokens to input characters. The FAQ carries the billing mechanics in plain words, including the new Text-to-Speech API at $15 per 1M characters.
Cohere
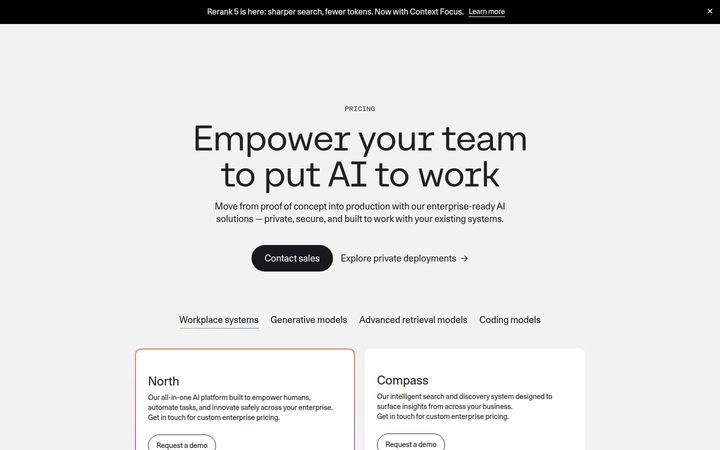
$3.00/instance/hrCohere prices for the enterprise in three shapes: custom contracts for its North and Compass platforms, reserved capacity on Model Vault at $3.00 to $7.00 an hour or $2,000 to $4,300 a month per instance, and pay-as-you-go tokens behind a Production API key. A four-way toggle sorts the page by buying job, and the FAQ carries the billing mechanics, down to an invoice at month end or at $250 of outstanding balance.
Deepgram
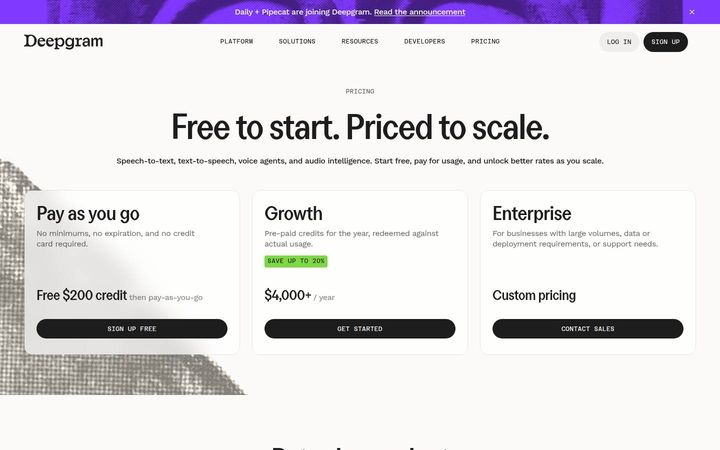
$0.0077/minDeepgram's page opens on "Free to start. Priced to scale." and three cards: Pay as you go with a Free $200 credit, Growth at $4,000+ / year in pre-paid credits for up to 20% off, and Enterprise at Custom pricing. A tabbed "Rates by product" section names the meter for each product, per second of audio, per 1,000 characters, or per minute of connection time, and a sixteen-question FAQ carries the billing mechanics, from hourly rates to the 10% overage premium.

Exa
$4/1k requestsExa prices its search API per thousand requests, with a rate for each endpoint: Lite Search $4, Auto Search $7, Deep Search $12, Contents $1 per 1k pages, Monitors $2 and Answer $5, plus $1 per 1k for each result above ten and for AI page summaries. Agent runs offer metered compute at $0.10 per ACU and six effort levels: five fixed from $0.012 to $1.00 per request and an Ultra level billed on usage. The plan cards divide access, throughput and compliance, and the rate card below them carries the price.
fal
From $0.0002/secondfal prices two products on one page with rate sheets in place of plans: GPU hours for serverless compute across six SKUs, and model APIs billed per output unit across video, image, audio and 3D. The "Units per $1" column turns seconds, tokens, images, megapixels, characters, generations and credits into one number a buyer compares directly.